<!-- callout:note -->Updated 23 September 2026
We corrected this post to match the product. Cost spike is now described as it works today. Quiet hours, the confidence rating and the unused-resources timeline were removed because they are not available.
Most teams find out about a cost spike one of two ways. Someone in finance forwards last month's invoice with a question mark next to a line item. Or an engineer notices a namespace looks busier than usual and starts digging. Both happen after the money is spent.
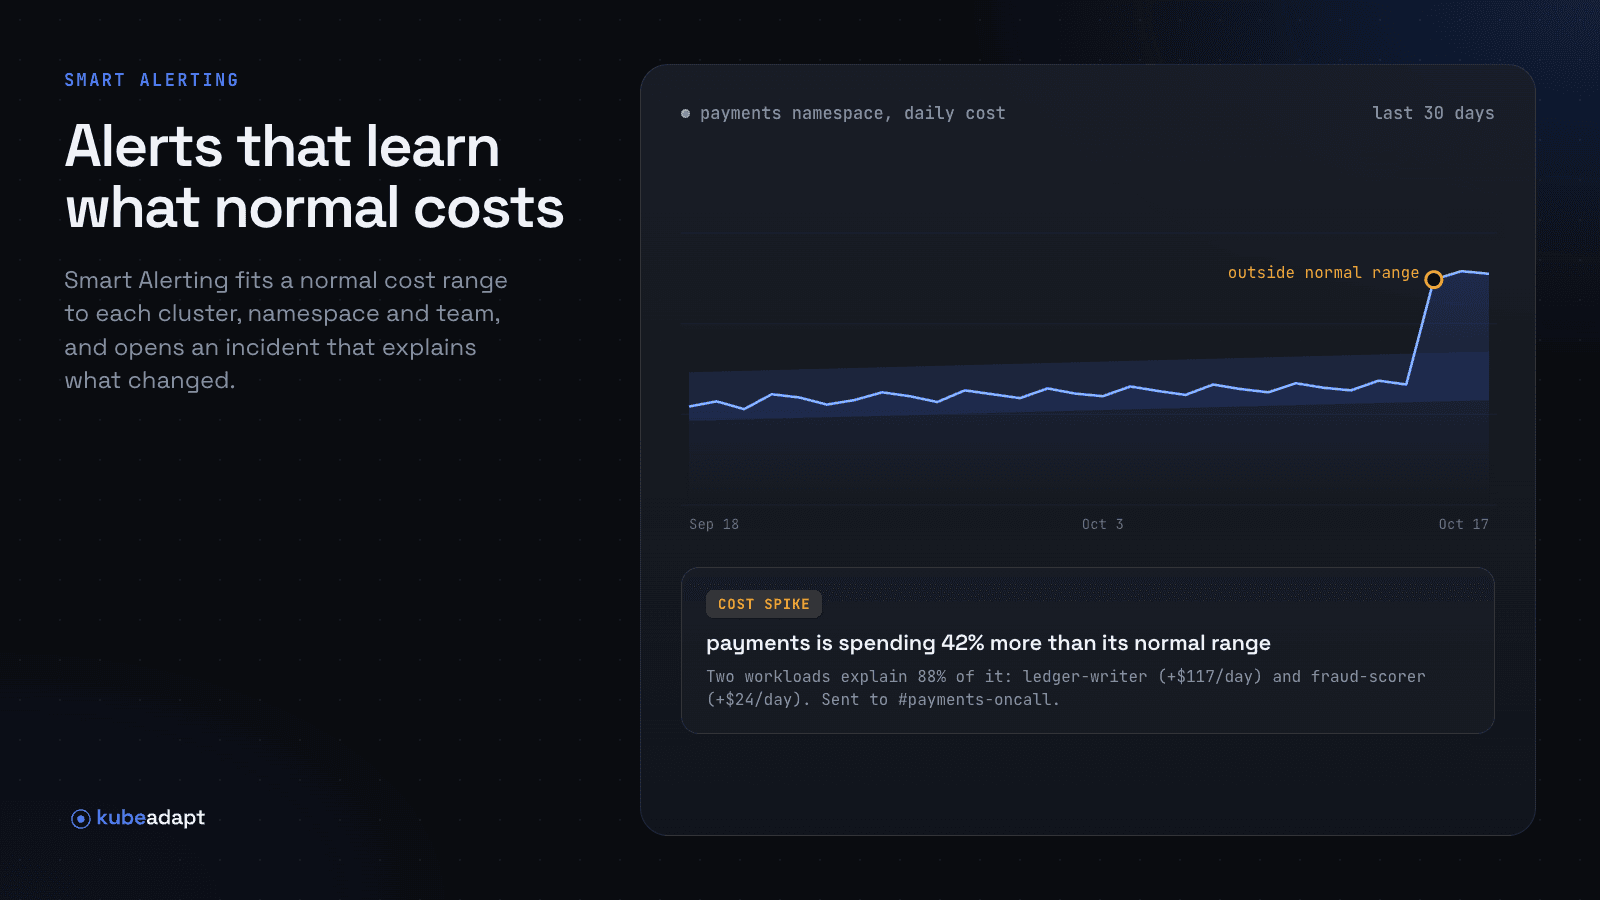
Smart Alerting watches the clusters, namespaces, teams and departments you choose. It fits a normal cost range to each one's own history and opens an incident when spend moves outside it, so nobody has to check a dashboard every morning or guess at a threshold.
Channels, policies and rules
Smart Alerting has three pieces, kept separate so you can reuse each one instead of rebuilding it for every alert.
A channel is where an alert goes: Slack, email or a webhook, which is signed with HMAC-SHA256 when you set a signing secret. A policy decides how an alert is delivered: immediately, in a daily digest, or in-app only. It also sets a daily cap, so one bad afternoon doesn't become fifty notifications. A rule ties a scope (organization, cluster, namespace, team or department) to one or more alert types and a policy.
You can attach one policy to as many rules as you want. Change the delivery behavior once and every rule using it follows. The rule editor also stops you from creating two rules for the same scope, so nobody gets notified twice for one change.
Cost spike doesn't ask you to guess a threshold
Most alerting tools ask you to type in a number: notify me if spend crosses $X. That number is usually wrong within a month. A Black Friday traffic spike looks like an incident to a static threshold and like a normal Tuesday to the team that planned for it.
Cost spike learns each scope's normal range from its own daily cost history, including weekday patterns. It opens an incident only when spend stays outside that range and the excess clears a minimum dollar amount. A scope needs about two weeks of daily history before detection starts. Until then it stays quiet rather than firing false alarms.
Two alert types for fixed conditions
Not everything needs to adapt. Two alert types handle cases where a fixed condition is exactly what you want.
Budget threshold opens an incident when spend crosses a percentage of a budget you set (monthly, quarterly or annual), with notifications at 50%, 80%, 90% and 100%. You choose whether the budget counts fully loaded cost, including shared overhead, or workload cost alone.
New expensive workload flags a newly deployed workload once it crosses a monthly cost you set, after a minimum age so short-lived pods don't trip it. Workloads owned by operator custom resources (Argo, Spark, Ray, Kubeflow) are skipped by default, and you can exclude other owner kinds, such as Jobs and CronJobs, on the rule.
Unused-resources alerts are not available yet. We'd rather ship idle-resource detection once it has been tested against enough real clusters than ship one that buries you in false positives.
Every incident explains itself
An incident firing is only half the job. The other half is telling you whether it matters and what caused it.
When Smart Alerting opens an incident, it rates how unusual the change is against the last 30 days: unprecedented, rare, normal or common. It tells you whether the increase is concentrated in one workload or spread across many, and whether nodes or workloads drove it. It also shows how much of the dollar change it can explain and how much is still unaccounted for, so you know when to trust the summary and when to look closer yourself.
Each contributing workload gets a likely cause: a CPU or memory request change, a replica count change, a new image, a changed autoscaler bound, an OOM burst or a crashloop. That's the difference between "spend went up 14%" and "the checkout service's replica count doubled at 2 AM and nobody scaled it back down."
Explanations in plain language
With Kubeadapt AI turned on, every incident has an Explain this incident button. It streams a plain-language write-up of what happened, why it matters and what to do next, built from the findings above. Kubeadapt AI is off by default; that changelog entry lists exactly what data the model sees and how to turn it on. Usage is capped per workspace, and when the cap is reached the incident says so instead of hiding the button.
Delivery you can check
An alert that disappears into a channel nobody watches is worse than no alert. Each incident keeps a log of every notification attempt: delivered, failed and retried, suppressed because the rule was snoozed or muted, deferred into a digest, or kept in-app, with a preview of the message that was sent. Each channel also shows its delivery health, so you can see when a Slack webhook starts failing.
Getting started
Add a Slack webhook, an email address or a webhook as your first channel, create a policy, then add a rule for the scopes you care about. Cost spike works from each scope's existing cost history, so detection starts as soon as a scope has about two weeks of it.
Start free or read the Smart Alerting docs.